Constructing Time Series Networks
Mohammed Saqr
University of Eastern FinlandSonsoles López-Pernas
University of Eastern FinlandManuel J. Gómez
University of MurciaSource:
vignettes/constructing-time-series-networks.Rmd
constructing-time-series-networks.RmdIntroduction
Time series analysis traditionally represents temporal data as observations indexed by time, with attention directed to quantities such as level, variation, dependence, and change. A network representation offers a complementary view: it replaces, or augments, the explicit time index with a relational structure in which nodes stand for observations, temporal states, or local windows, and edges encode a defined relationship between them. That relationship may be geometric visibility, numerical similarity, a state transition, a co-occurrence, or a weighted dependence. A time series therefore does not have a single canonical network. The network that results is determined jointly by the chosen representation and by the structural question that representation is designed to answer.
The tsn package provides a set of these
representations while keeping the modelling choices explicit at every
step. discretize() maps continuous observations onto a
finite set of ordered states and so yields a symbolic version of the
series. trend() characterizes local direction and separates
short-range increase, decrease, stability, and turbulence.
vg() constructs a visibility graph, in which observations
are joined when the geometry of the series makes them mutually visible.
tsn() is the general distance-network constructor over
complete series, local windows, or individual observations; this
vignette applies it to overlapping windows joined by their
similarity.
Once a series has been reduced to a sequence of states, its dynamics
can be examined through transition network analysis.
ts_tna() builds a transition network whose edges carry
conditional transition probabilities. ts_ftna() builds the
corresponding frequency network, ts_cna() a co-occurrence
network, and ts_atna() an attention-weighted transition
network. These four constructions summarize different properties of the
same symbolic sequence and are complementary rather than
interchangeable. Finally, series_networks() extracts and
indexes the network model attached to each source series, retaining the
model type, the shared state alphabet, and the provenance needed to
trace a network back to its data.
Every representation in this vignette is developed on one fixed
segment of one measured variable, so that the constructions can be
compared without any change in the underlying data. Network figures are
produced by the package’s plot() methods through
cograph, and the four transition-network constructors
require the Nestimate package; both are optional and
used only where noted.
| Scientific question | Function | Result | What it captures |
|---|---|---|---|
| How can a continuous series be represented as a sequence of discrete states? | discretize() |
Tidy state table | Maps continuous observations onto a finite, ordered state alphabet, making recurring levels and ranges explicit. |
| How does the series change locally over time? | trend() |
Tidy trend table | Labels each observation by its local direction: increase, decrease, stability, or turbulence. |
| Which observations are connected by geometric visibility? | vg() |
Visibility network | Connects observations that can “see” each other over the intervening values. |
| Which time windows are similar in value or shape? | tsn() |
Distance network | Relates local windows by their proximity, exposing repeated or structurally similar segments. |
| How likely is one state to be followed by another? | ts_tna() |
Transition network (TNA) | Weights directed edges by the conditional probability of each successive transition. |
| How often does the series move from one state to another? | ts_ftna() |
Frequency network (FTNA) | Weights directed edges by the observed count of each successive transition. |
| Which states co-occur within the sequence? | ts_cna() |
Co-occurrence network (CNA) | Uses undirected edges to represent state co-occurrence, ignoring direction. |
| Which transitions receive the greatest attention weight? | ts_atna() |
Attention-weighted network (ATNA) | Weights directed edges by model-assigned attention rather than raw counts. |
| How is each network associated with its source series? | series_networks() |
Indexed model collection | Organizes extracted models by source series while preserving their correspondence and provenance. |
In short, discretize() defines the
states, trend() describes local
direction, vg() describes geometric
visibility, and tsn() describes similarity
between temporal windows. The ts_tna() family then
builds transition networks from the state sequence, differing only in
the quantity assigned to their edges, and series_networks()
indexes the results by source series.
Data
The esm_srl data set bundled with the package is an
example of experience-sampling, or intensive longitudinal, data: 41
students were prompted repeatedly, usually more than once a day, and
asked to rate their momentary self-regulation, motivation, and anxiety
on 0-100 scales. Each of its 2,820 rows is one such momentary report.
The data are fully anonymized — the participant identifiers are
fictional names and the calendar dates have been shifted by a constant
offset, so within-person spacing is preserved while no real dates or
identities remain. The nine indicators span self-regulation
(planning, monitoring, effort,
regulation), motivation (efficacy,
value, motivated, enjoyment), and
anxiety; a derived day_type column marks
weekday and weekend reports.
This vignette follows a single one of these signals for a single
student: the momentary anxiety ratings of the participant
recorded as Jamal, who reported 79 occasions in total. To keep every
network small enough to read in full, the analysis uses only his first
60 reports, which each verb selects by name from the data frame. Passing
the data frame rather than a bare vector preserves the recorded order of
the observations, and that order is what every method below treats as
the flow of time.
data("esm_srl", package = "tsn")

anxiety <- head(subset(esm_srl, name == "Jamal"), 60)

dim(anxiety)
#> [1] 60 13
These 60 reports span 31 anonymized calendar days. The anxiety ratings occupy the full observed range 0 to 100, with a median of 49, a mean of 47.0, and a standard deviation of about 27, so they spread across a wide band rather than clustering near a single value. The segment carries no systematic trend: the first twenty reports average 44.9 and the last twenty average 46.3, essentially unchanged. The representations that follow should therefore be read as descriptions of short-run fluctuation around a roughly constant level, not of a rising or falling series. The distinction matters for interpretation, because several of the constructions below, in particular the visibility graph and the trend labels, respond to the local rises and falls of the series rather than to its overall direction.
Transition Network Analysis
Transition Network Analysis starts by turning the observed series
into a finite sequence of states. The aim is not to discard the measured
values but to obtain a symbolic representation in which dynamics can be
studied as movement among a fixed set of states.
discretize() performs this step, assigning each observation
to one state and returning one tidy row per observation.
Here the default quantile discretization splits the values into three
empirical groups, labelled Low, Middle, and
High. The resulting sequence keeps the temporal order of
the observations and replaces their continuous values with ordered
categorical states.
states <- discretize(
  data = anxiety,
  series = "anxiety",
  labels = c("Low", "Middle", "High")
)

states
#> <tsn_states> quantile discretization (transform: none): 60 observations, 3 states
#>       id time     value  state probability
#>  anxiety    1 18.279570    Low           1
#>  anxiety    2 58.064516 Middle           1
#>  anxiety    3 16.129032    Low           1
#>  anxiety    4 56.989247 Middle           1
#>  anxiety    5 55.913978 Middle           1
#>  anxiety    6 70.967742   High           1
#>  anxiety    7 74.193548   High           1
#>  anxiety    8 56.989247 Middle           1
#>  anxiety    9  8.602151    Low           1
#>  anxiety   10 50.537634 Middle           1
summary(states)
#>    state count proportion mean_value
#> 1    Low    20  0.3333333   17.04301
#> 2 Middle    20  0.3333333   45.69892
#> 3   High    20  0.3333333   78.38710
Each row records the source identifier, the time index, the observed
value, the assigned state, and an assignment probability. The
probability column reports the confidence of the
assignment: it equals 1 for a hard partition such as the quantile rule
used here, and takes values in the unit interval for probabilistic
discretizers such as gaussian or kde. Because
the state labels follow the ordering of the values, Low,
Middle, and High retain a strict ordinal
meaning. Quantile boundaries need not divide tied observations into
exactly equal groups; in this segment they happen to do so, with 20
observations in each state and state means of 17.0, 45.7, and 78.4.
The state sequence is the intermediate object from which every transition network below is built. Its three states become the network nodes, and each adjacent pair of observations defines one possible state-to-state transition. The four constructors that follow all read this same sequence; what differs between them is the quantity placed on the edges.
plot(states, type = "ribbon")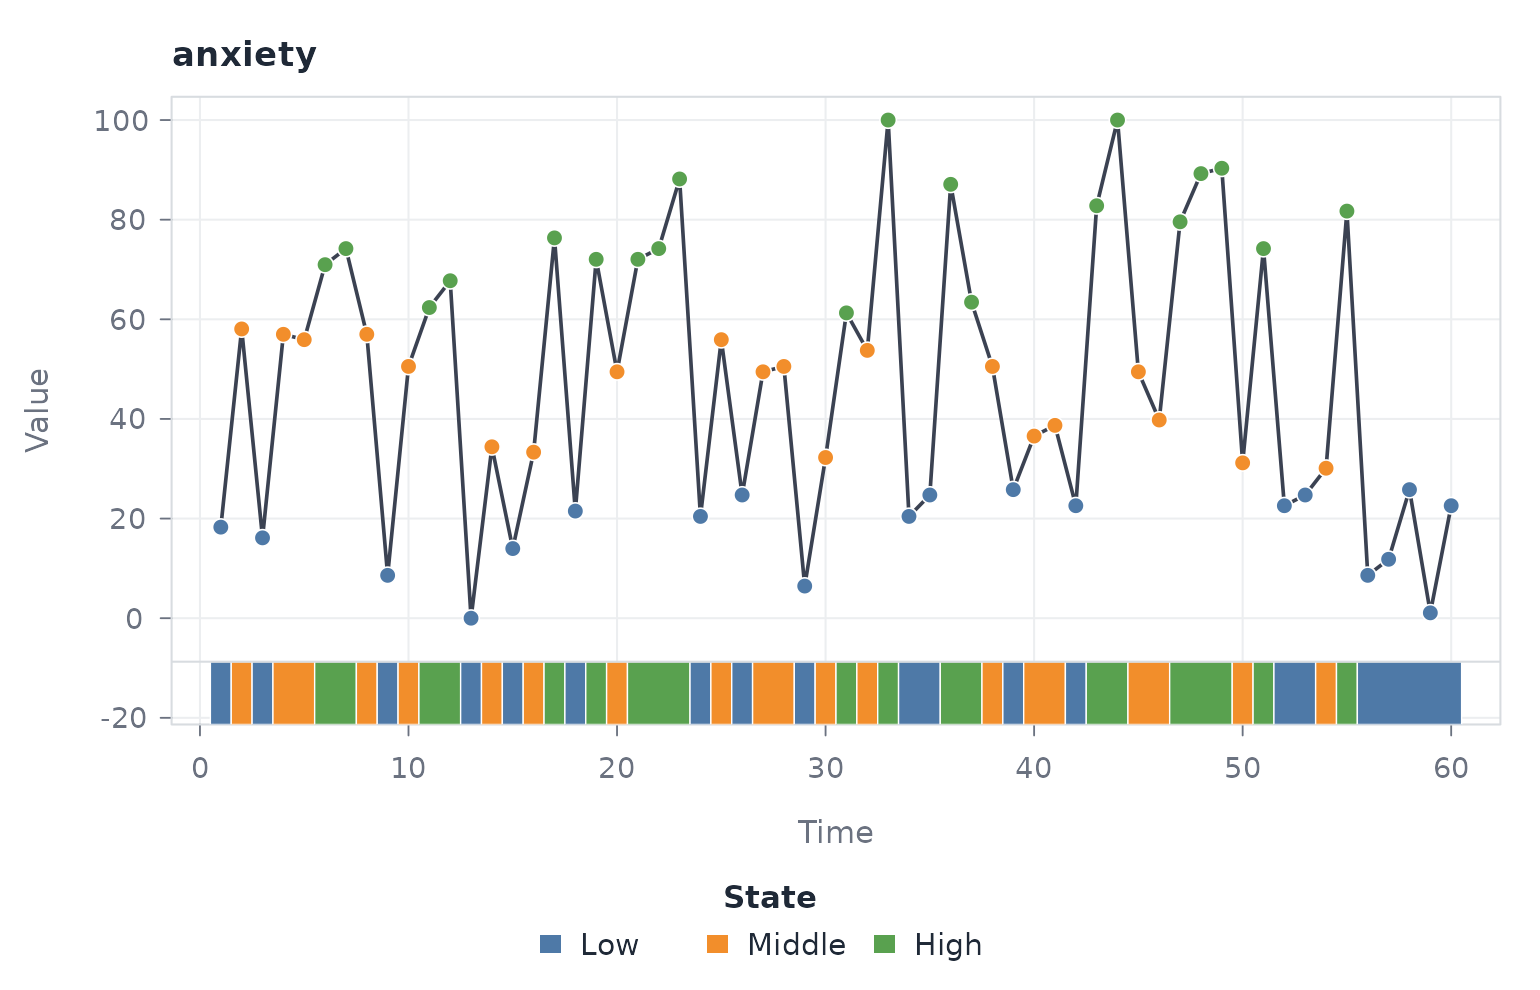
The ribbon view places the discrete states beneath the measured series, so the correspondence between an observation and its assigned state stays visible without a full-panel overlay obscuring the values themselves.
Transition probabilities with ts_tna()
ts_tna() builds a directed network in which an edge runs
from the current state to the next, weighted by the conditional
probability of that transition. Each row of the weight matrix is a
probability distribution over the possible next states, so the outgoing
weights of a state sum to one.
probabilities <- ts_tna(states)

probabilities
#> Transition Network (relative probabilities) [directed]
#>   Weights: [0.158, 0.526]  |  mean: 0.333
#>
#>   Weight matrix:
#>            Low Middle  High
#>   Low    0.316  0.526 0.158
#>   Middle 0.350  0.200 0.450
#>   High   0.300  0.300 0.400
#>
#>   Initial probabilities:
#>   Low           1.000  ████████████████████████████████████████
#>   Middle        0.000
#>   High          0.000
The diagonal entries measure persistence, the probability that the
next observation stays in the current state: 0.316 for Low,
0.200 for Middle, and 0.400 for High.
Comparing these with the marginal state proportions (each exactly one
third here) separates persistence from mere prevalence.
High persists above its marginal share, so a high-anxiety
report is more likely to be followed by another one than random ordering
would imply. Low sits near its share, while
Middle falls well below it: after a mid-range report the
series usually leaves, most often upward (Middle to
High is 0.450). The single largest transition probability
is Low to Middle at 0.526 — low anxiety
resolves toward the middle of the scale rather than holding.
plot(probabilities)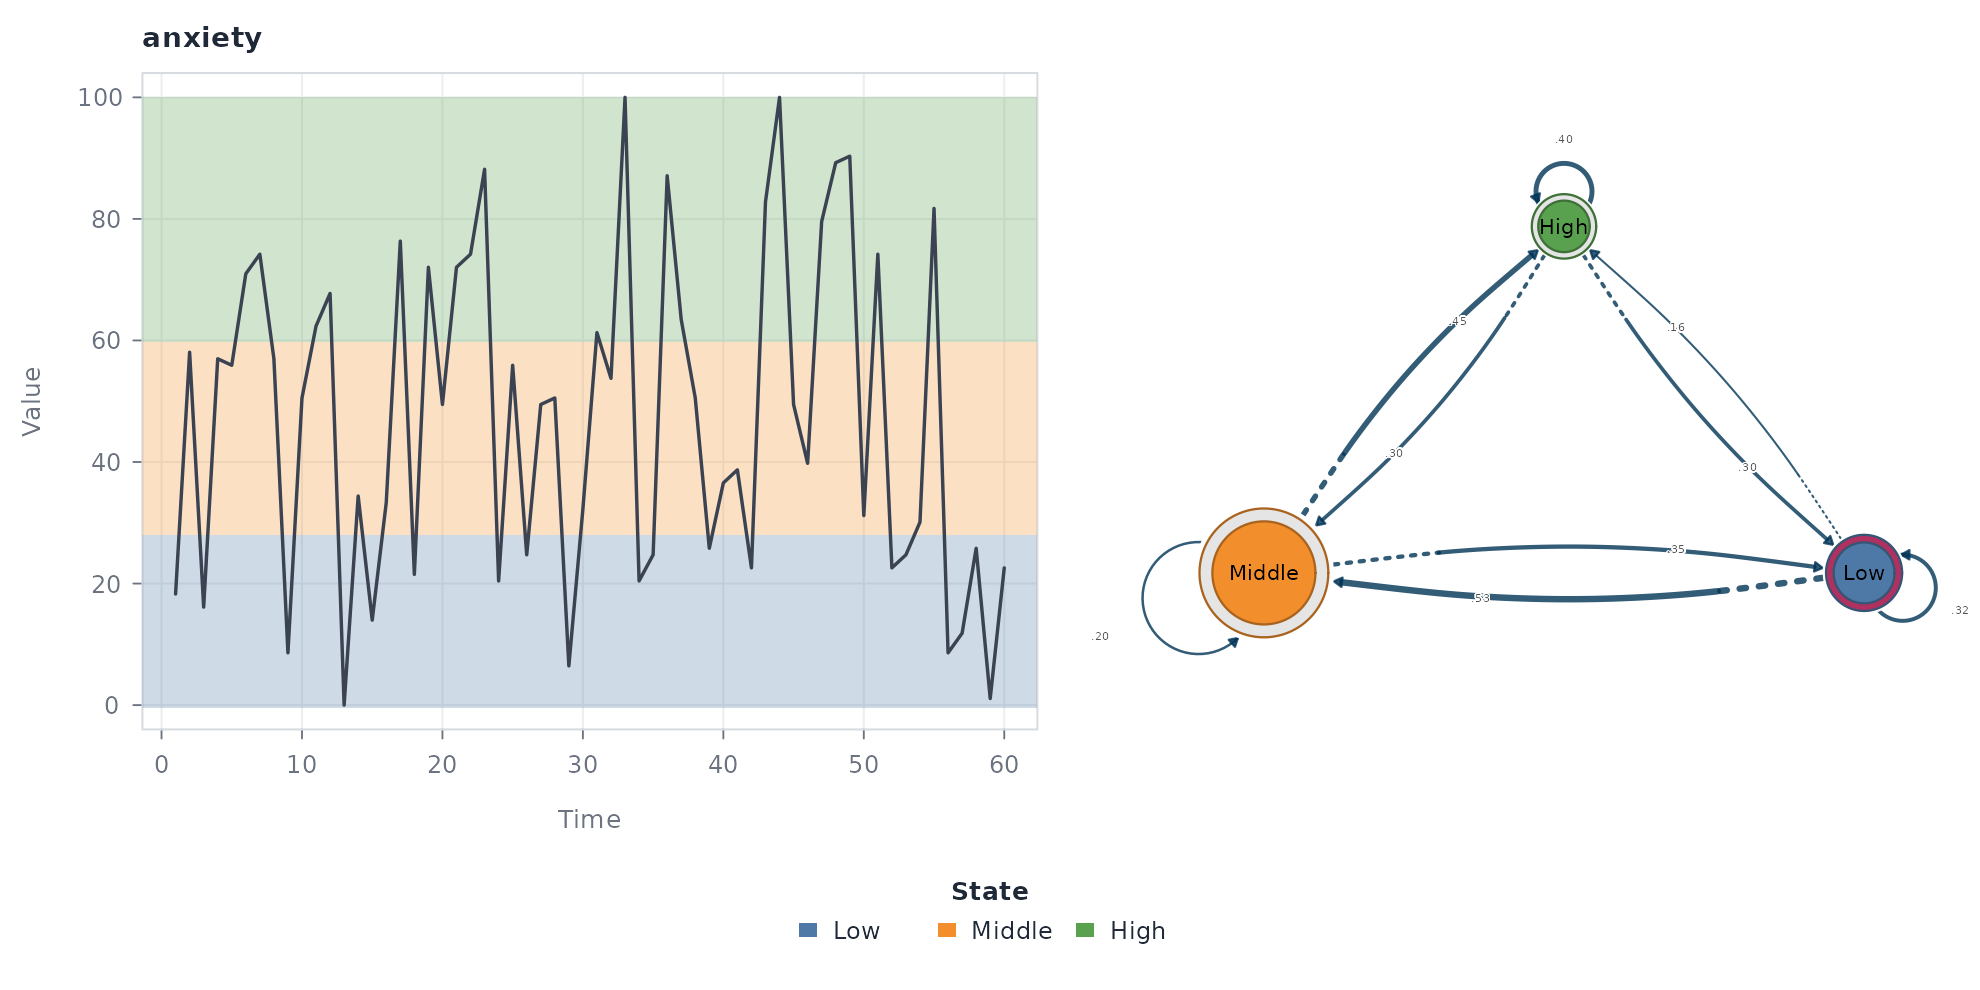
Row normalization is what makes this representation interpretable. Each row is the conditional distribution of the next state given the current one, so the outgoing patterns of different states remain comparable even though the states may have different marginal frequencies. A sequence of 60 observations is thereby reduced to three nodes and the directed relationships among them, with the temporal order retained as the basis for the estimates.
Transition frequencies with ts_ftna()
ts_ftna() weights each directed edge by the observed
count of the corresponding transition, without the row normalization
applied by ts_tna(). The network therefore preserves the
absolute number of times each transition occurred.
counts <- ts_ftna(states)

counts
#> Transition Network (frequency counts) [directed]
#>   Weights: [3.000, 10.000]  |  mean: 6.556
#>
#>   Weight matrix:
#>          Low Middle High
#>   Low      6     10    3
#>   Middle   7      4    9
#>   High     6      6    8
#>
#>   Initial probabilities:
#>   Low           1.000  ████████████████████████████████████████
#>   Middle        0.000
#>   High          0.000
The 60 observations form 59 adjacent pairs, so the count matrix sums
to 59. The most frequent single transition is Low to
Middle, which occurs 10 times; the largest self-transition,
High to High, occurs 8. No row is dominated by
its own diagonal — Middle follows itself only 4 times
against 16 departures — so persistence, although present for
High, does not dominate the raw counts here. The frequency
and probability networks describe the same transitions but answer
different questions: the frequency network reports how
often each transition occurred, whereas the probability network
reports how likely it is given the current state.
plot(counts)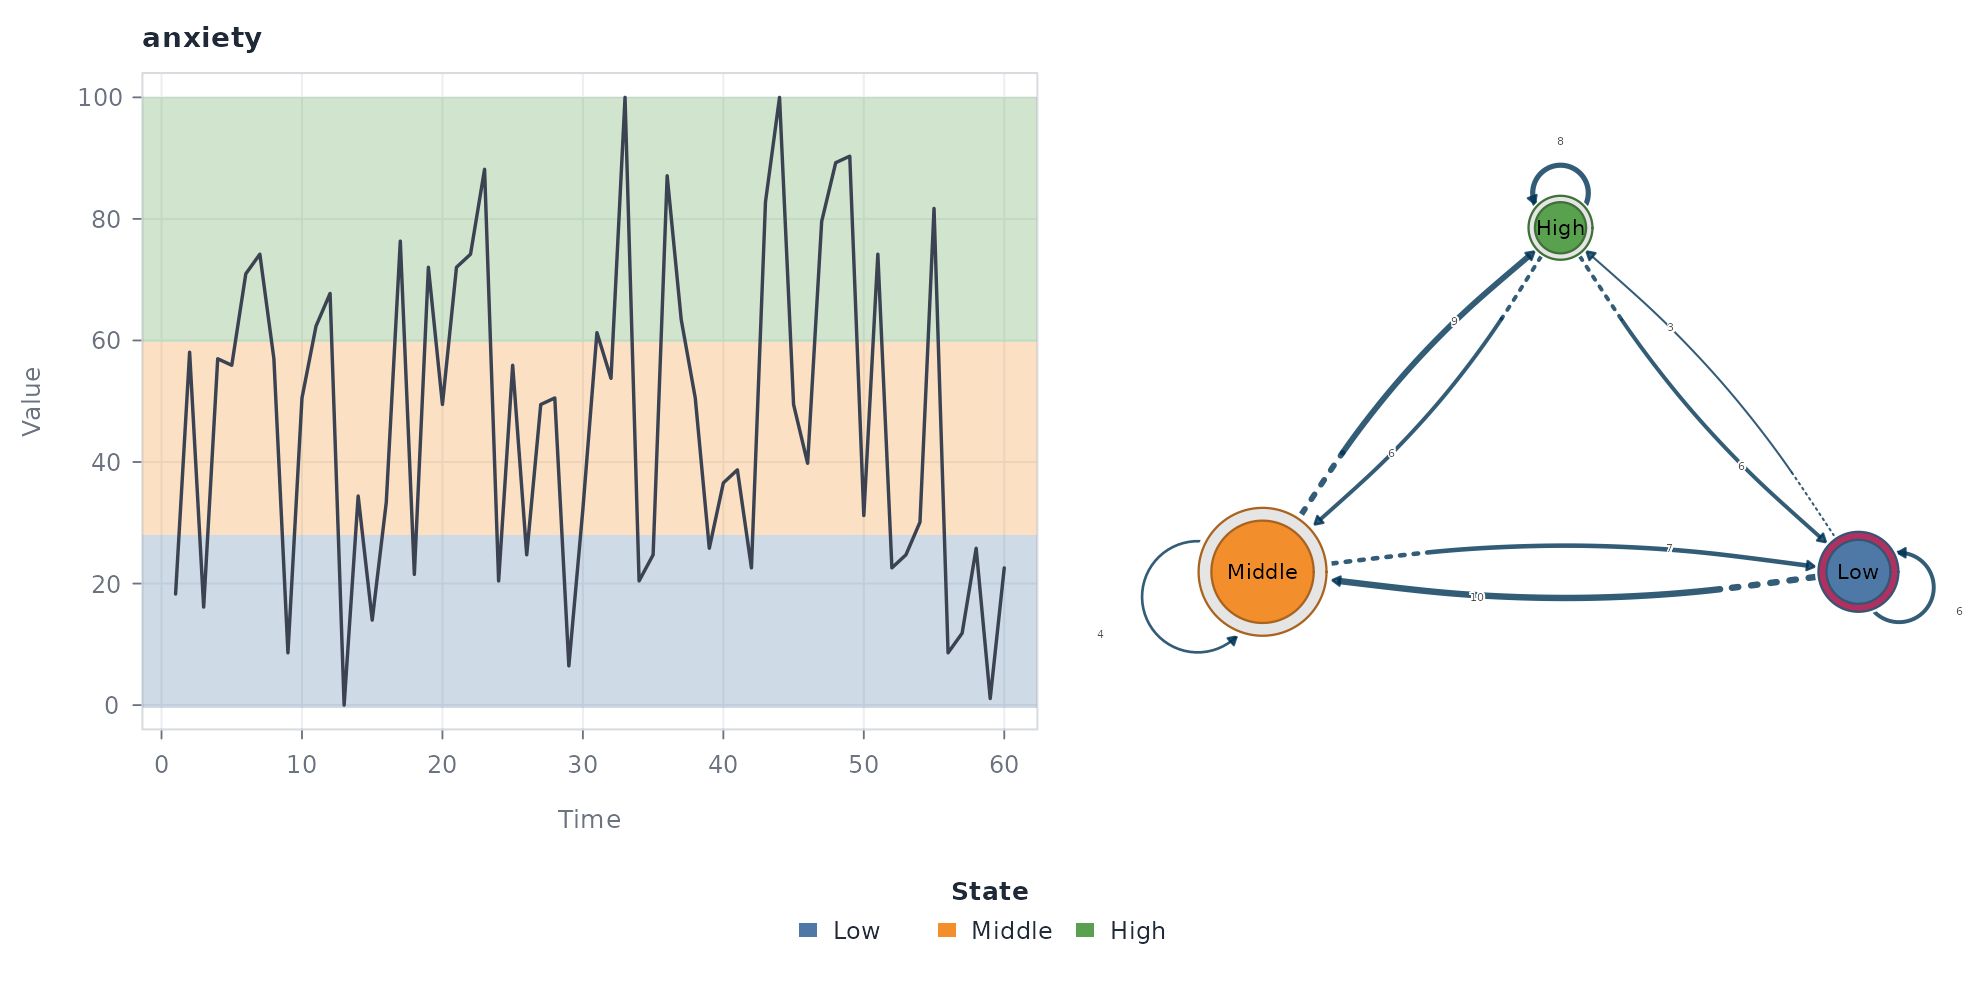
State co-occurrence with ts_cna()
ts_cna() builds an undirected, symmetric network whose
edges measure how strongly two states occur together, without regard to
the order in which they appear. It answers a different question from the
directed transition networks.
cooccurrence <- ts_cna(states)

cooccurrence
#> Co-occurrence Network [undirected]
#>   Weights: [190.000, 400.000]  |  mean: 295.000
#>
#>   Weight matrix:
#>          Low Middle High
#>   Low    190    400  400
#>   Middle 400    190  400
#>   High   400    400  190
For a single sequence, these co-occurrence counts follow directly
from the marginal state frequencies. An off-diagonal entry is the
product of the two state counts, so with 20 observations per state every
between-state weight is 20 * 20 = 400; a diagonal entry
counts the unordered pairs within a state, so every self-weight is
20 * 19 / 2 = 190. The network therefore reflects the
composition of the state alphabet rather than the temporal direction of
transitions — with exactly equal state counts it is completely uniform.
A strong edge means the two states are both common, not that one tends
to follow the other.
plot(cooccurrence)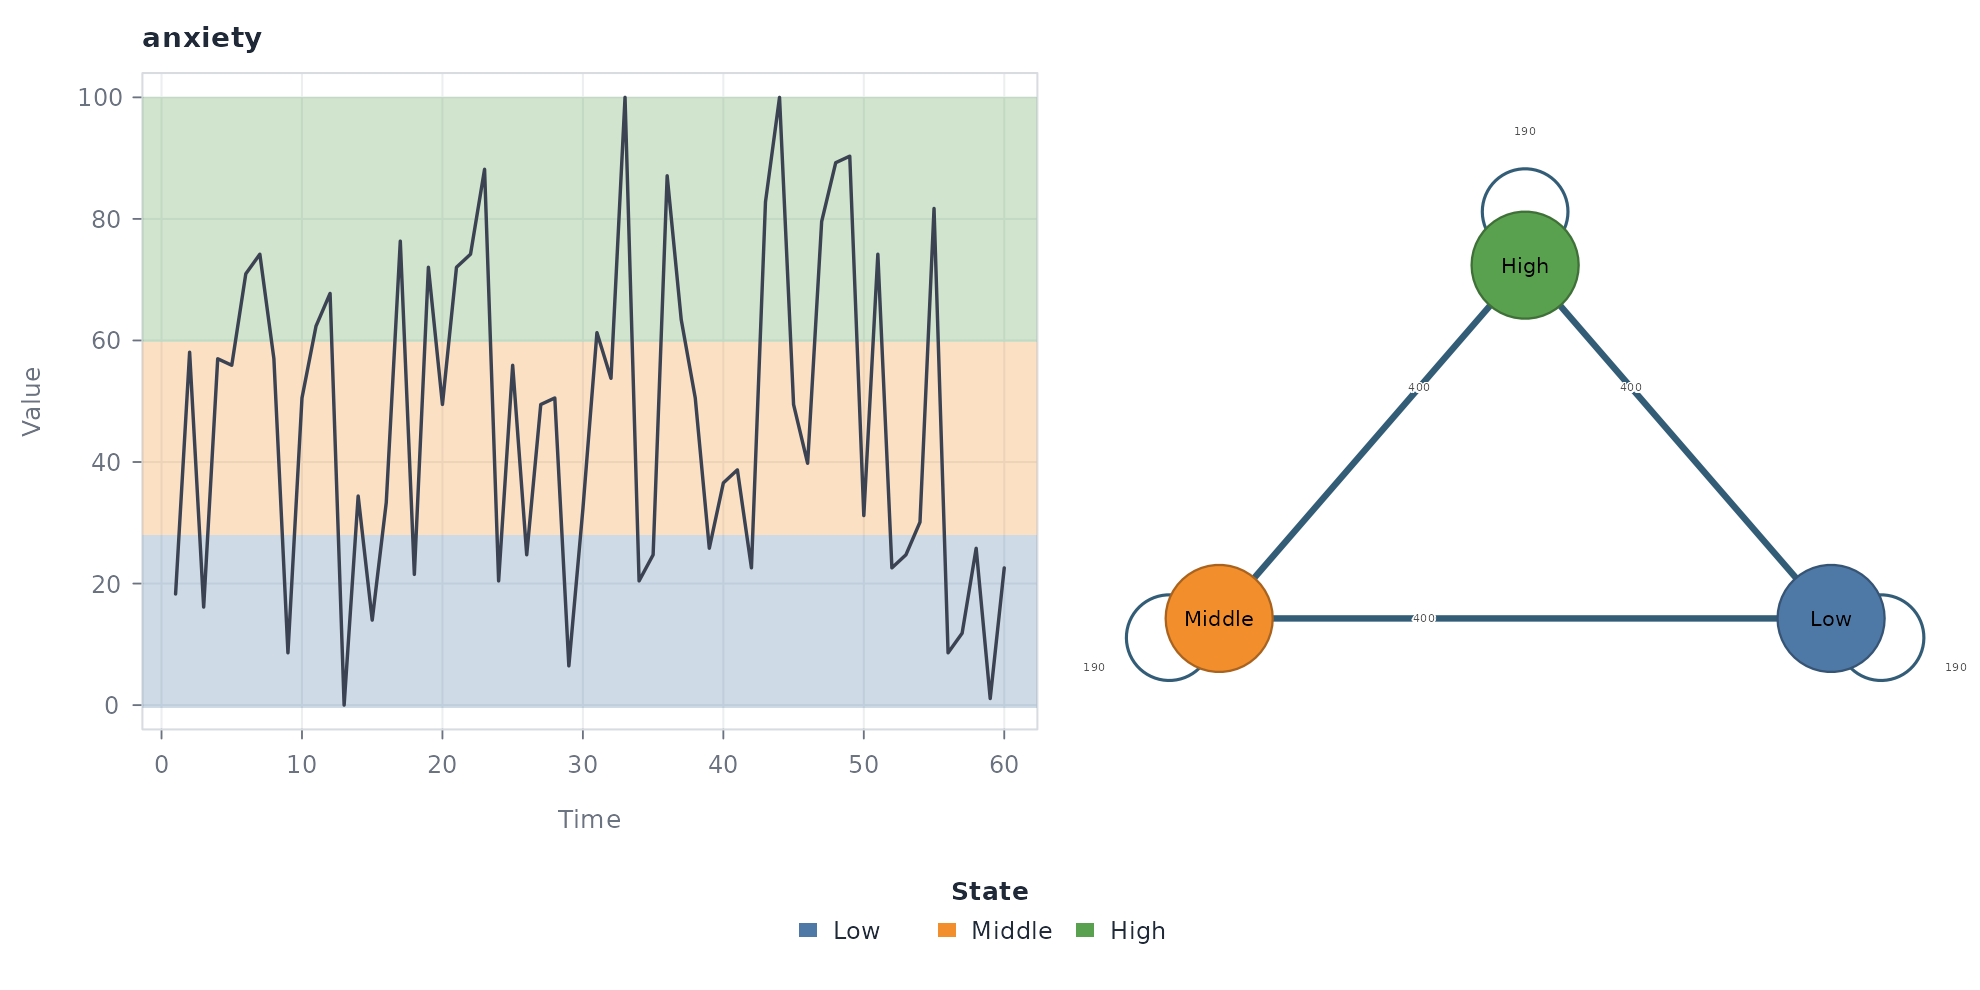
The symmetric drawing makes the distinction explicit: an edge carries no source-to-target direction, in contrast to the transition networks above.
Attention-weighted transitions with ts_atna()
ts_atna() assigns each transition an attention weight
rather than a count or a probability. The edge weights are accumulated
attention values and are not on the scale of either the frequency or the
probability network.
attention <- ts_atna(states)

attention
#> Attention Network (decay-weighted transitions) [directed]
#>   Weights: [2.462, 5.000]  |  mean: 3.778
#>
#>   Weight matrix:
#>            Low Middle  High
#>   Low    3.470  4.793 2.462
#>   Middle 3.771  2.867 5.000
#>   High   3.738  3.726 4.172
#>
#>   Initial probabilities:
#>   Low           1.000  ████████████████████████████████████████
#>   Middle        0.000
#>   High          0.000
The weights range from 2.462 to 5.000. Unlike the frequency and
probability networks, the largest weights here are off-diagonal: the
strongest attention-weighted transitions are Middle to
High (5.000) and Low to Middle
(4.793), and the persistence diagonals are not the dominant entries in
their rows. The attention mechanism consequently redistributes emphasis
away from self-transitions, and the weights should be read on the
model’s own attention scale rather than compared directly with counts or
probabilities.
plot(attention)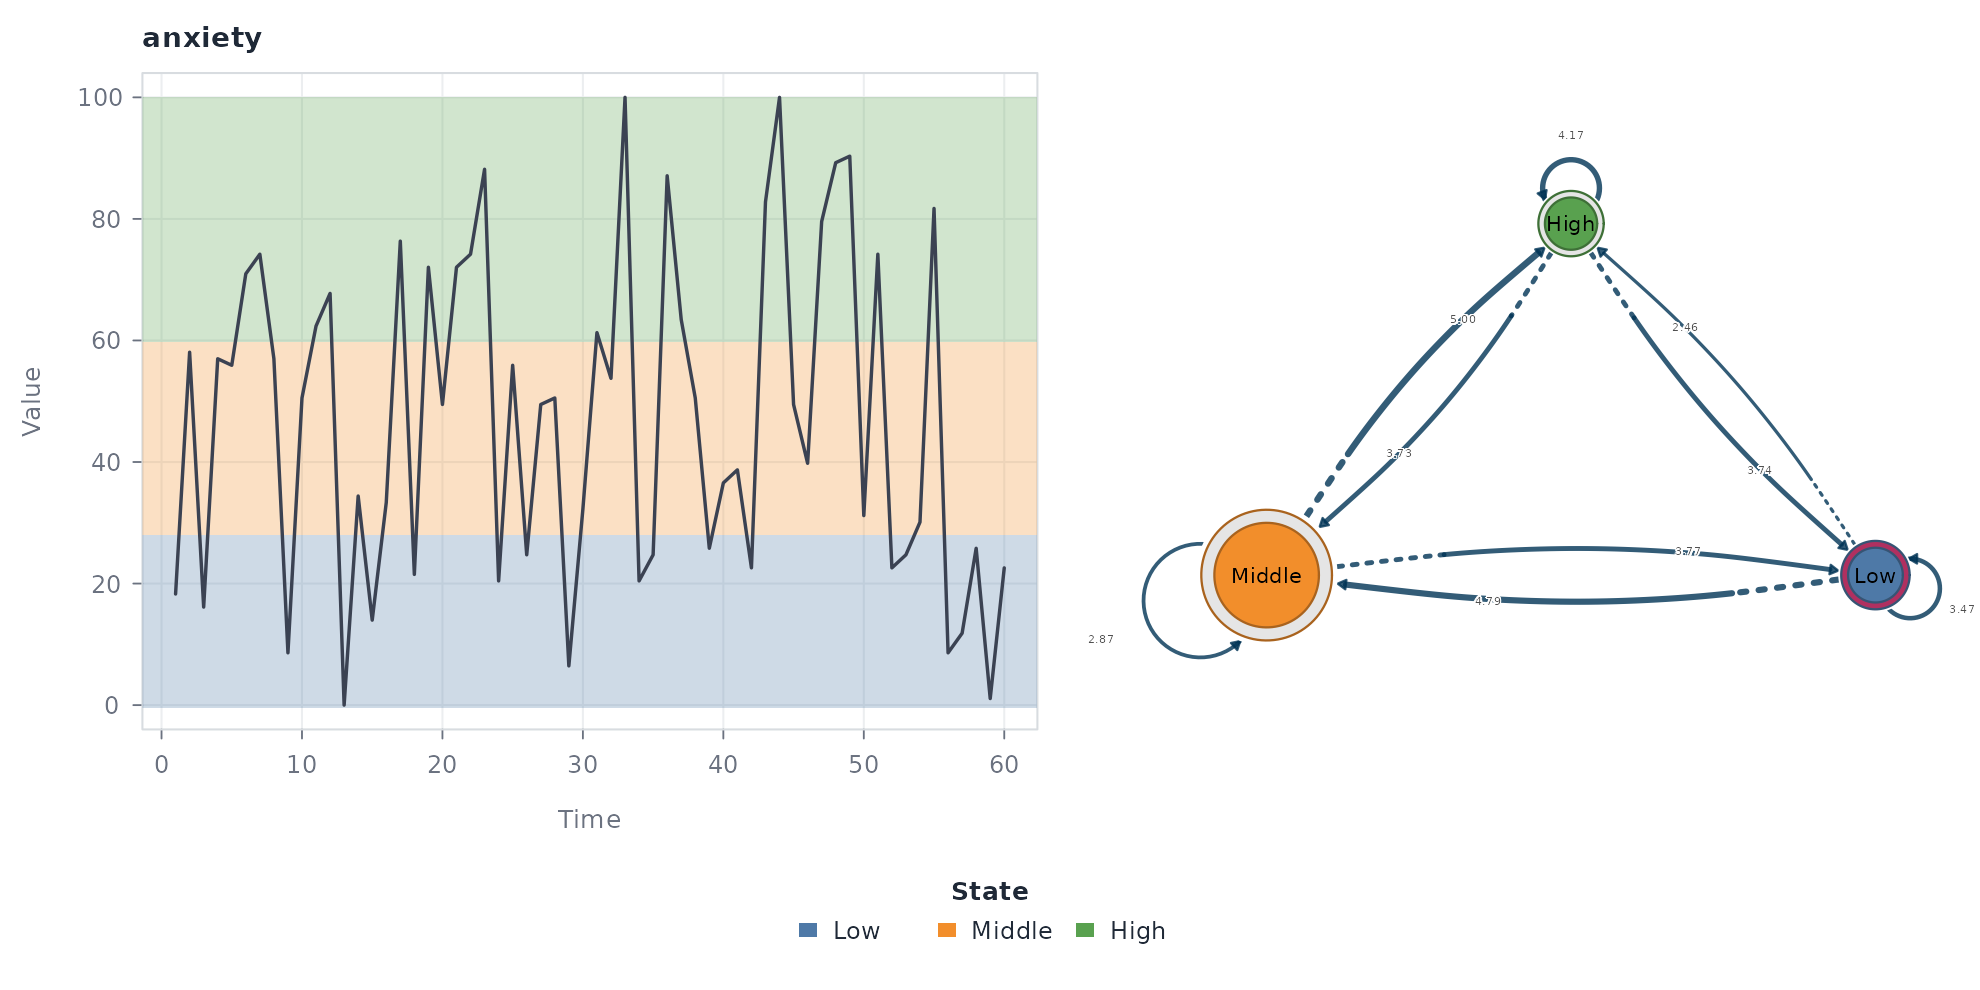
Indexing the model with series_networks()
series_networks() returns an indexed collection of the
network models attached to the source series. It is designed for
analyses that extract networks across many series at once, where the
index preserves the link between each series and its model. With a
single input series it returns one entry, corresponding to
anxiety.
individual <- series_networks(probabilities)

individual
#>   series type observations states edges
#>  anxiety  tna           60      3     9
The index records the source series, the network type, and the number of observations, states, and edges. For the transition-probability network the three states generate nine directed relationships, the six between distinct states plus the three self-transitions.
plot(individual)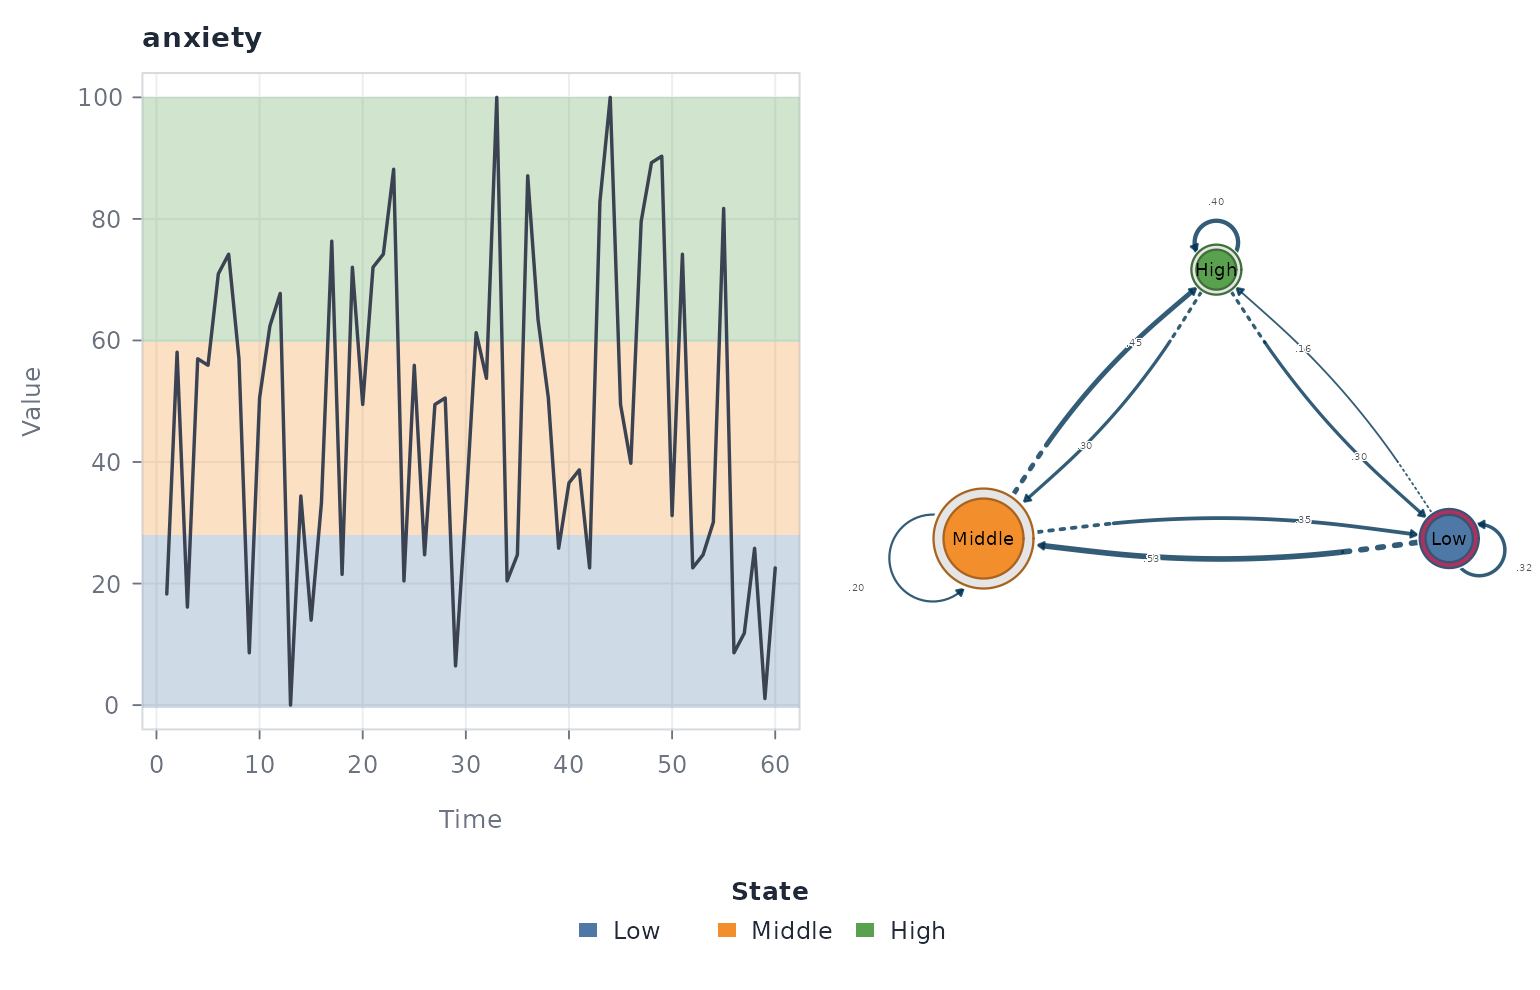
The collection thus provides a higher-level handle on the extracted networks while keeping their provenance. Given several source series, the same structure organizes and compares their models systematically.
Local direction with trend()
trend() estimates a rolling local slope and labels each
observation as Ascending, Descending,
Flat, Turbulent, Missing Data, or
Initial. The window is adaptive and defaults to one tenth
of the series length, which is 6 observations here, and the default
Theil-Sen slope limits the influence of isolated extreme ratings.
directions <- trend(
  data = anxiety,
  series = "anxiety"
)

directions
#> <tsn_trend> slope (robust), window 6: 60 observations across 1 series
#>       id time     value    metric      state
#>  anxiety    1 18.279570        NA    Initial
#>  anxiety    2 58.064516        NA    Initial
#>  anxiety    3 16.129032  9.408602  Ascending
#>  anxiety    4 56.989247  5.734767  Ascending
#>  anxiety    5 55.913978  6.989247  Ascending
#>  anxiety    6 70.967742 -1.075269 Descending
#>  anxiety    7 74.193548 -5.107527  Turbulent
#>  anxiety    8 56.989247 -3.225806 Descending
#>  anxiety    9  8.602151  1.792115  Ascending
#>  anxiety   10 50.537634  1.792115  Turbulent
summary(directions)
#>        state count proportion
#> 1  Ascending    24 0.40000000
#> 2 Descending    21 0.35000000
#> 3  Turbulent    10 0.16666667
#> 4    Initial     5 0.08333333
Ascending is the most common label with 24 observations,
followed by Descending with 21, Turbulent with
10, and Initial with 5. The near balance between ascending
and descending positions is what a segment without drift should produce:
local direction keeps reversing rather than accumulating in one
direction. No observation earns the Flat label at all — in
this segment the local slope is never both small and steady for a full
window, which is itself a description of how restless the momentary
ratings are. Initial marks the leading positions that lack
a complete centered window, and Missing Data would mark
absent values, of which this segment has none.
plot(directions)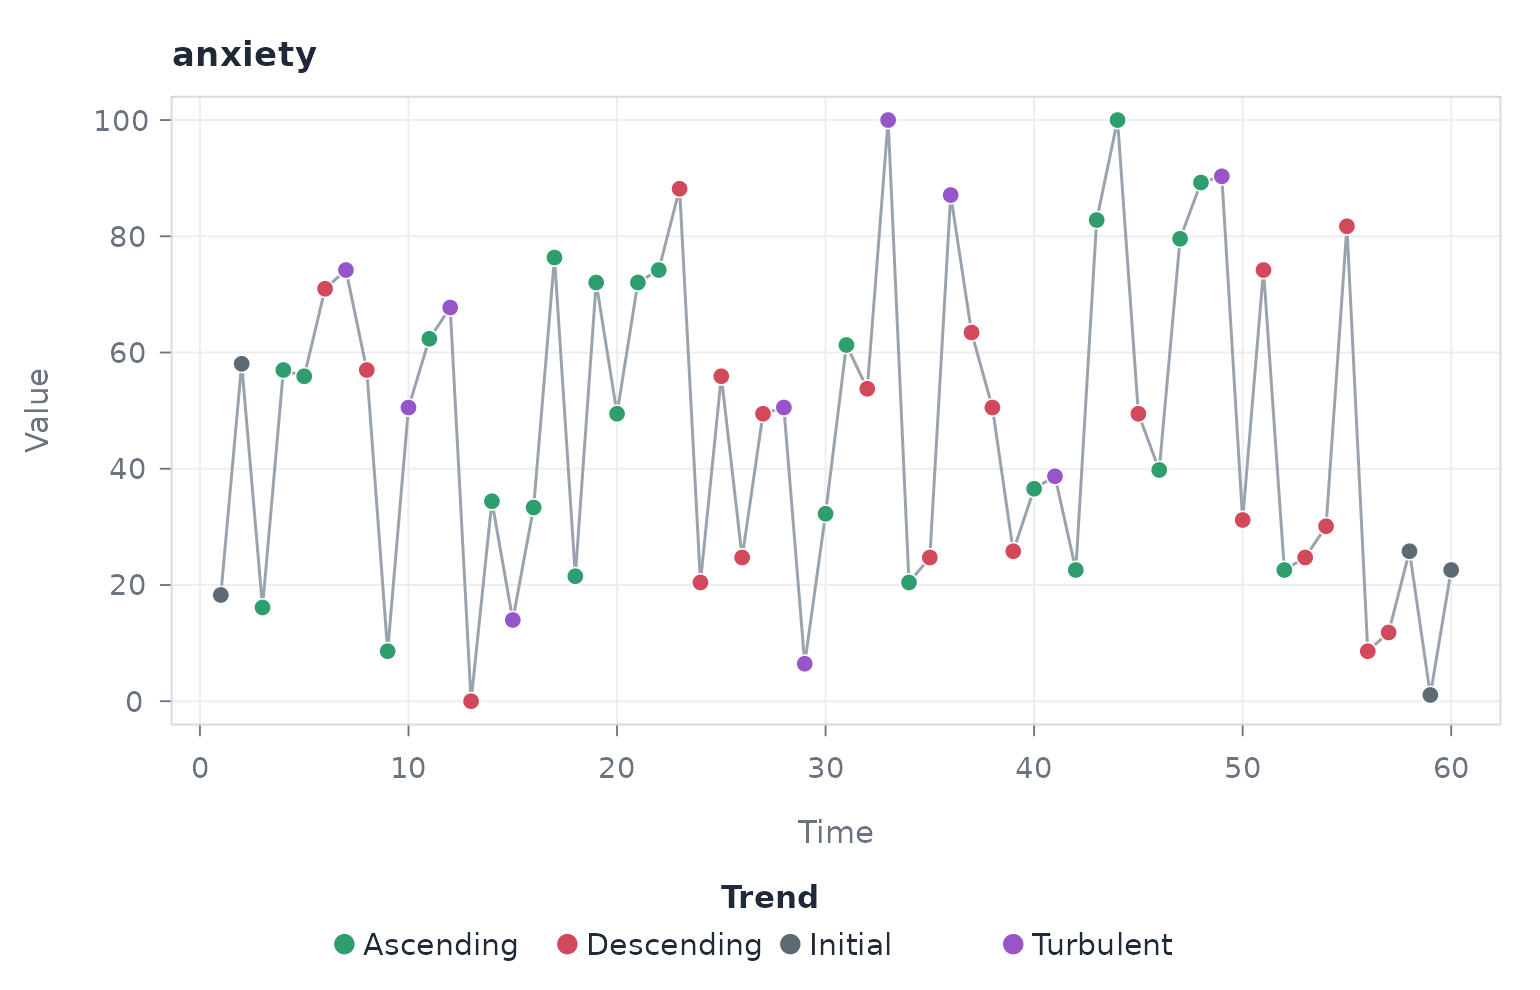
The default plot colours each observation by its trend label.
plot(directions, type = "panels")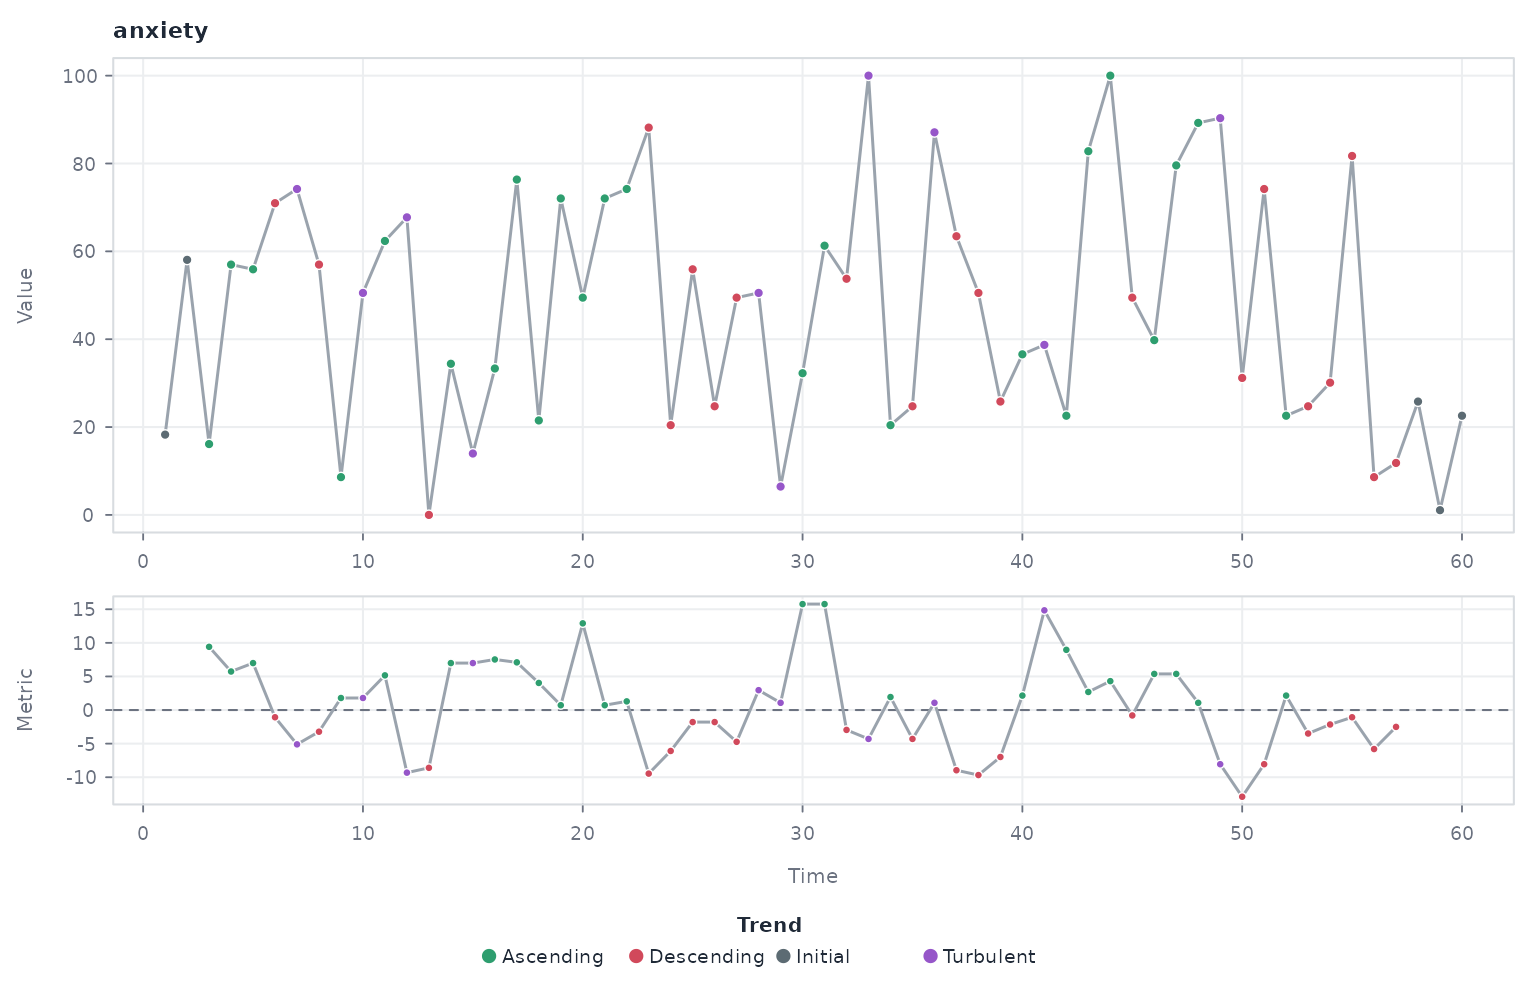
The panel view places the rolling metric below the measurements, so the points at which the metric crosses the flat band can be checked against the assigned direction.
Visibility with vg()
vg() treats each observation as a node. Under natural
visibility, two points are joined when the straight line between their
values stays above every intervening point. Under horizontal visibility,
they are joined only when every intervening value lies below both
endpoints, a strictly stronger condition.
natural <- vg(
  data = anxiety,
  series = "anxiety"
)

summary(natural)
#>       method unit nodes dyads edges    density minimum_weight maximum_weight
#> 1 visibility time    60   144   144 0.08135593              1              1
#>   directed
#> 1    FALSE
The natural visibility graph has 60 nodes and 144 edges. At this length the edges remain distinguishable, so it can be drawn directly. Node size encodes degree, and the peaks accumulate the most connections because they stay visible over the smaller values around them.
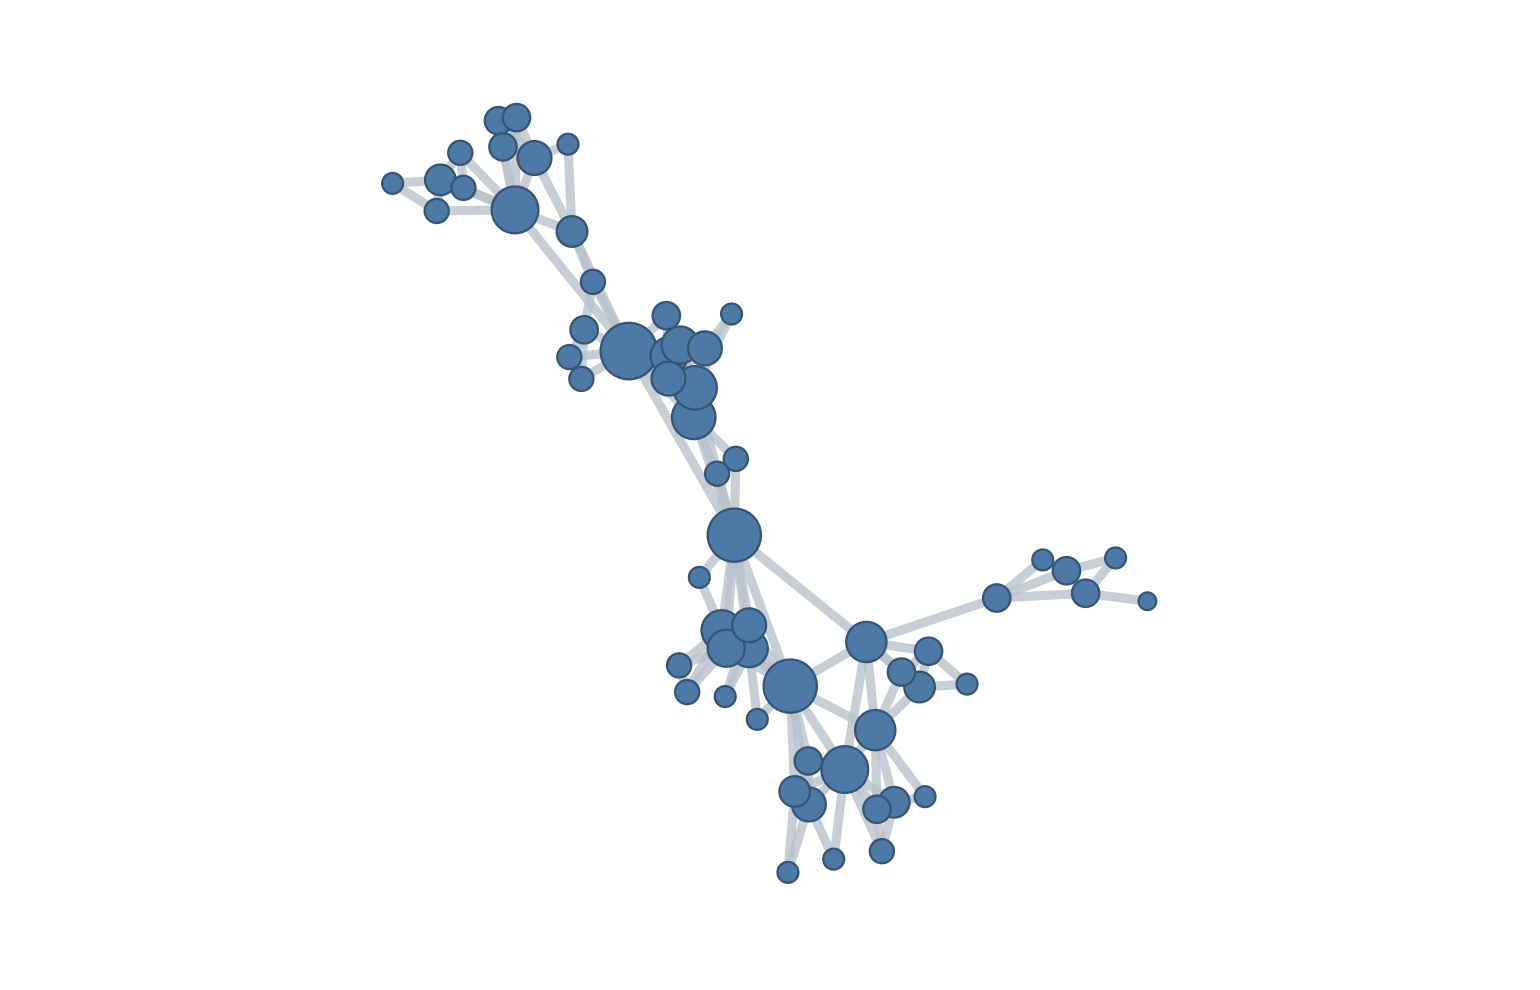
The horizontal rule keeps the same 60 nodes but fewer edges.
horizontal <- vg(
  data = anxiety,
  type = "horizontal",
  series = "anxiety"
)

summary(horizontal)
#>       method unit nodes dyads edges    density minimum_weight maximum_weight
#> 1 visibility time    60   106   106 0.05988701              1              1
#>   directed
#> 1    FALSE
It retains 106 of the 144 connections, removing the 38 that a natural line of sight can clear but a horizontal one cannot. The result keeps the temporal chain of consecutive observations while dropping the longer sightlines that only the natural view permits. In both graphs the edge weights are binary, since visibility either holds or it does not.
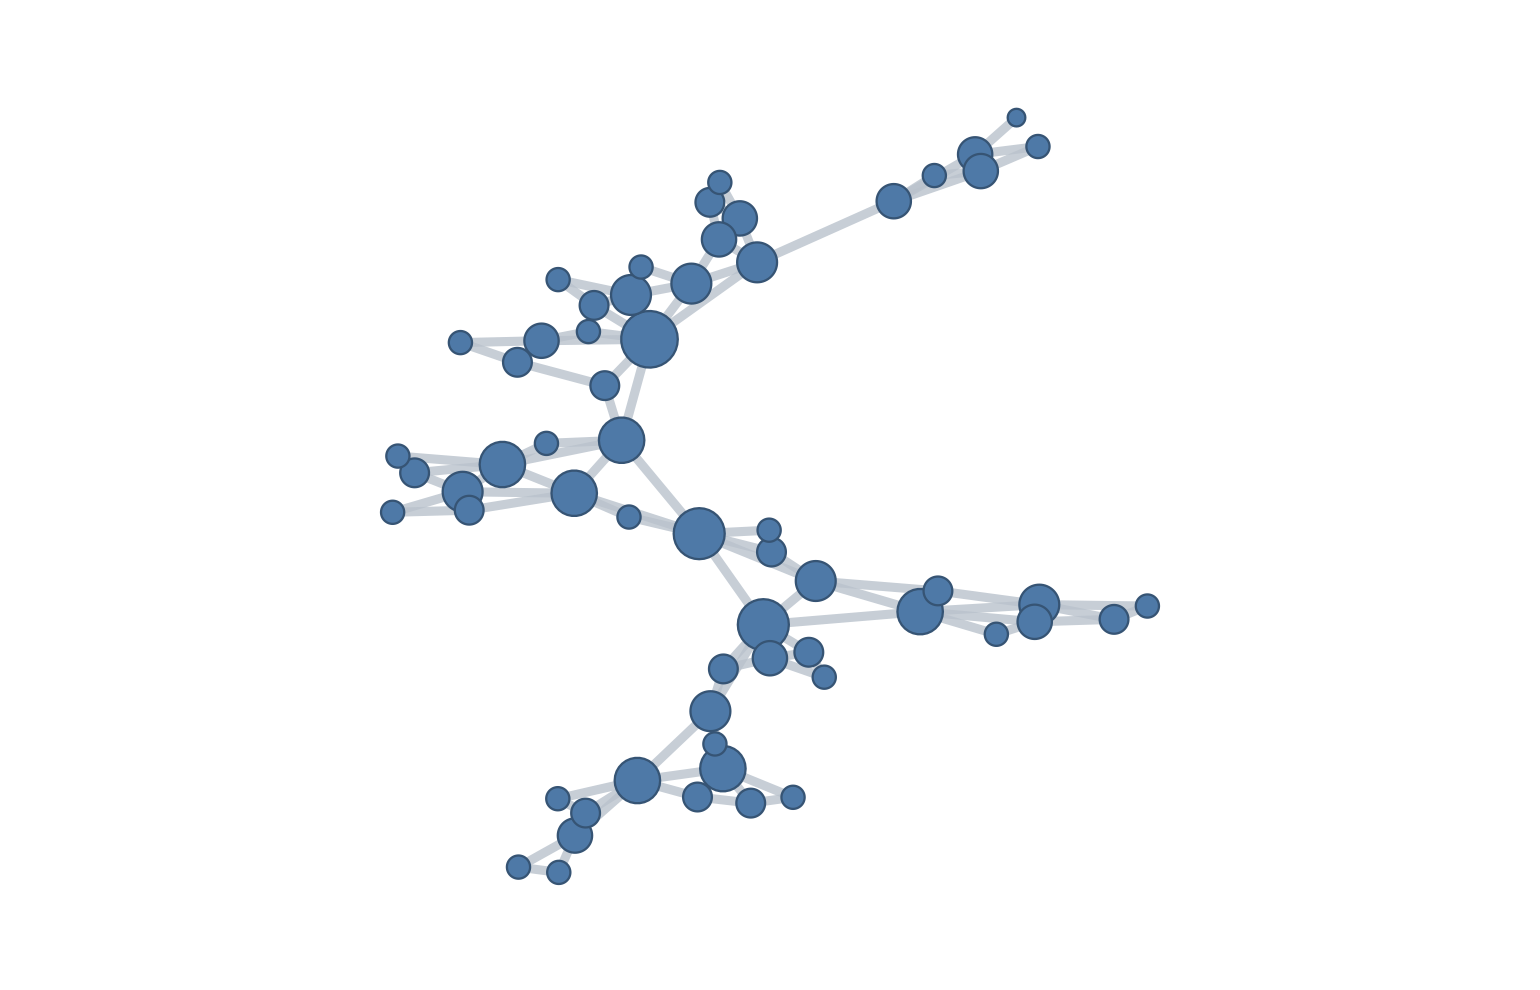
Every network also retains the series it was built from, which the source-series view recovers.
plot(horizontal, type = "series")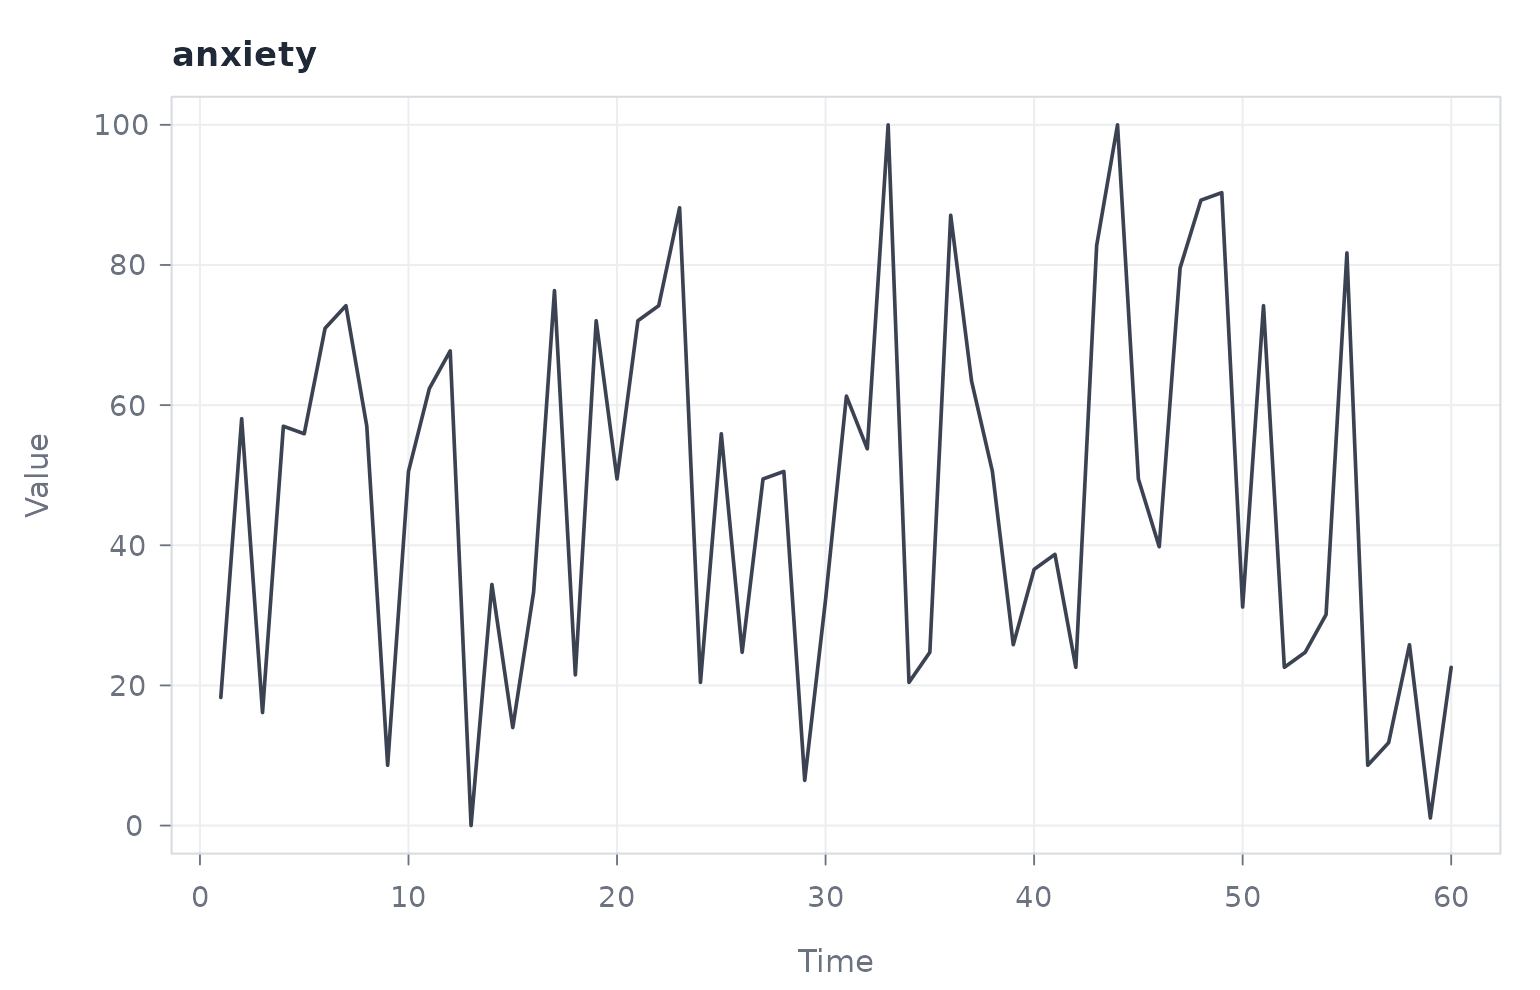
This view makes the short-run fluctuation that the visibility rule reads directly apparent.
Window similarity with tsn()
tsn() is the general distance-network constructor. With
method = "distance" a single measured series defaults to
sliding-window nodes. The window width defaults to one tenth of the
series length, which is 6 here, and a step of 2 yields 28 overlapping
windows.
windows <- tsn(
  data = anxiety,
  method = "distance",
  series = "anxiety",
  step = 2
)

summary(windows)
#>     method   unit nodes dyads edges density minimum_weight maximum_weight
#> 1 distance window    28   378   378       1    0.006923743     0.03540467
#>   directed
#> 1    FALSE
The default full connection rule evaluates and keeps all 378 window
pairs. Each edge weight is 1 / (1 + distance), so larger
weights mark more similar windows.
sparse <- tsn(
  data = anxiety,
  method = "distance",
  series = "anxiety",
  step = 2,
  connect = "nearest",
  neighbors = 2
)

summary(sparse)
#>     method   unit nodes dyads edges   density minimum_weight maximum_weight
#> 1 distance window    28   378    41 0.1084656     0.01240041     0.03540467
#>   directed
#> 1    FALSE
Nearest-neighbour sparsification keeps 41 edges and lowers the density from 1 to 0.108, retaining the strongest local similarities instead of drawing every pair.
plot(sparse)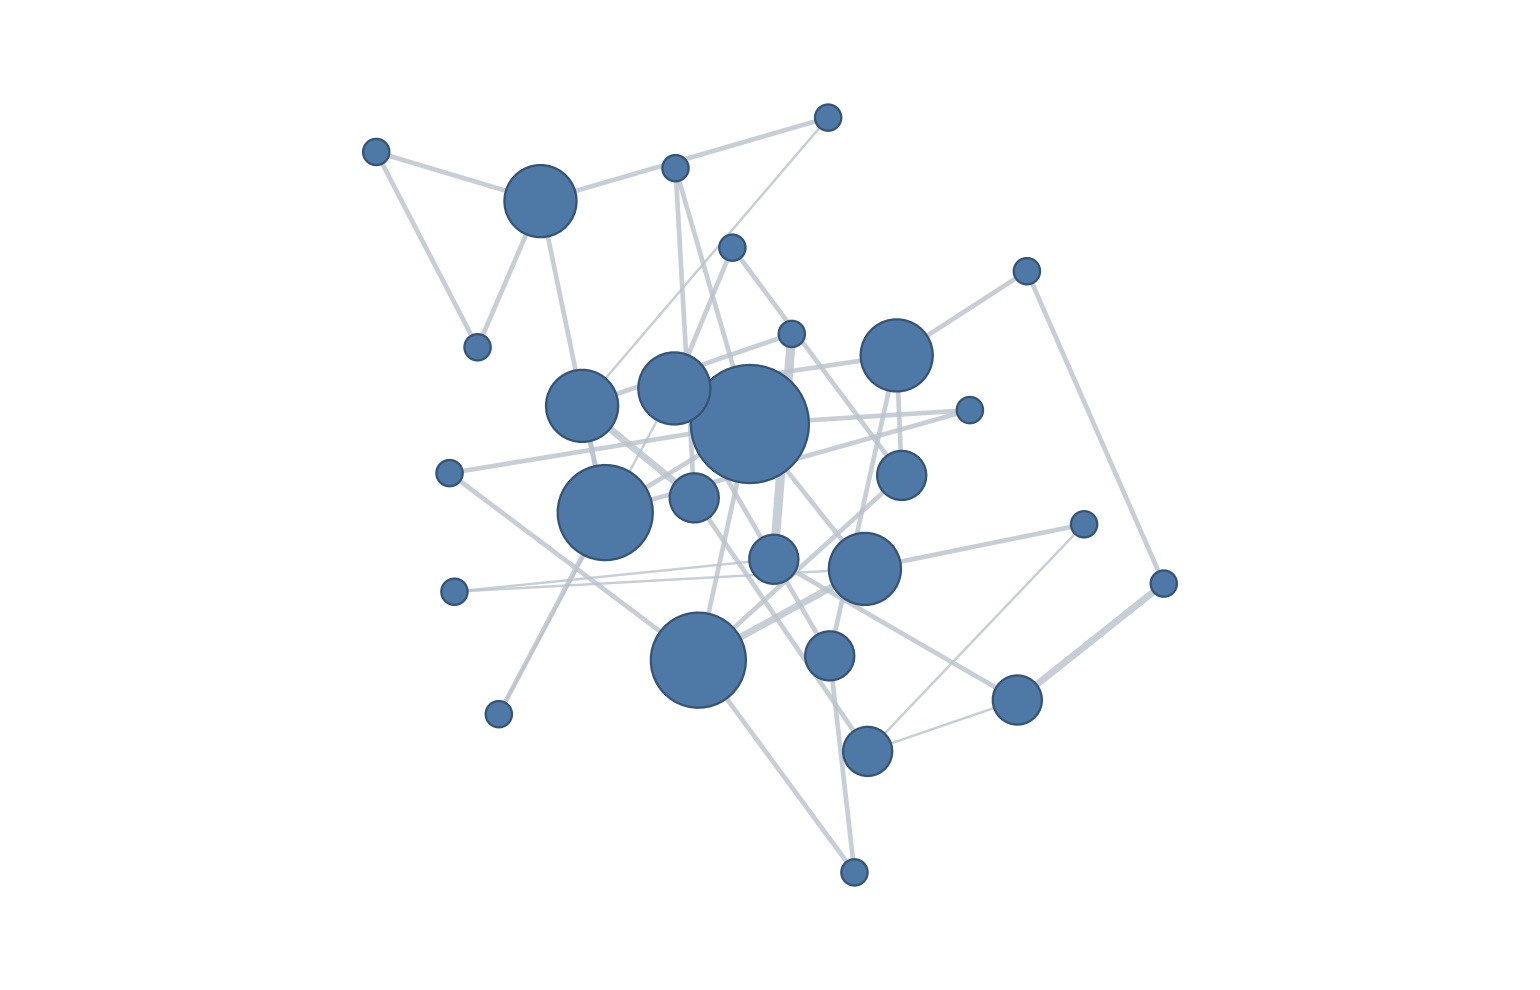
Only two of the retained edges join immediately adjacent windows; the others span anywhere from two to nineteen positions. Overlap in time therefore does not by itself determine similarity in value: windows far apart in the sequence can still be each other’s nearest neighbours.
The distance measure is itself a modelling choice. Dynamic time
warping aligns two windows by their shape, tolerating the shift or
stretch in time that Euclidean distance penalizes. Repeating the
sparsification under distance = "dtw" redraws the neighbour
graph on the same 28 windows.
warped <- tsn(
  data = anxiety,
  method = "distance",
  series = "anxiety",
  step = 2,
  distance = "dtw",
  connect = "nearest",
  neighbors = 2
)

summary(warped)
#>     method   unit nodes dyads edges   density minimum_weight maximum_weight
#> 1 distance window    28   378    37 0.0978836    0.007326873     0.04443383
#>   directed
#> 1    FALSE
The warped network keeps 37 edges against the Euclidean version’s 41, yet only 12 edges appear in both: the two rules connect largely different pairs of windows. Whether two windows count as similar therefore depends as much on the chosen distance as on the series itself.
plot(warped)